Research Papers

Are genomic language models all you need? Exploring genomic language models on protein downstream tasks

Sam Boshar | Evan Trop | Bernardo P. de Almeida | Liviu Copoiu | Thomas Pierrot

Bioinformatics (2024) Sep 2025
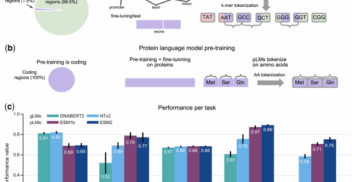
Motivation Large language models, trained on enormous corpora of biological sequences, are state-of-the-art for downstream genomic and proteomic tasks. Since the genome contains the information to encode all proteins, genomic language models (gLMs) hold the potential to make downstream predictions not only about DNA sequences, but also about proteins. However, the performance of gLMs on protein tasks remains unknown, due to few tasks pairing proteins with the coding DNA sequences (CDS) that can be processed by gLMs. Results In this work, we curated five such datasets and used them to evaluate the performance of gLMs and proteomic language models (pLMs). We show that gLMs are competitive and even outperform their pLMs counterparts on some tasks. The best performance was achieved using the retrieved CDS compared to sampling strategies. We found that training a joint genomic-proteomic model outperforms each individual approach, showing that they capture different but complementary sequence representations, as we demonstrate through model interpretation of their embeddings. Lastly, we explored different genomic tokenization schemes to improve downstream protein performance. We trained a new Nucleotide Transformer (50M) foundation model with 3mer tokenization that outperforms its 6mer counterpart on protein tasks while maintaining performance on genomics tasks. The application of gLMs to proteomics offers the potential to leverage rich CDS data, and in the spirit of the central dogma, the possibility of a unified and synergistic approach to genomics and proteomics.

Multi-Agent Reinforcement Learning with Selective State-Space Models

Jemma Daniel | Ruan John de Kock | Louay Ben Nessir | Sasha Abramowitz | Omayma Mahjoub | Wiem Khlifi | Juan Claude Formanek | Arnu Pretorius

AAMAS 2025 Sep 2025
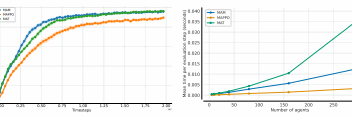
The left-hand plot in Figure 1 compares MAM, MAT, and MAPPO, aggregated over all tasks and environments. MAM achieves performance on par with MAT, the current state-of-the-art, while learning faster.

Sable: a Performant, Efficient and Scalable Sequence Model for MARL

Omayma Mahjoub | Sasha Abramowitz | Ruan de Kock | Wiem Khlifi | Simon du Toit | Jemma Daniel | Louay Ben Nessir | Claude Formanek | Louise Beyers | Liam Clark | Arnu Pretorius

ICML 2025 Jul 2025
Figure 1. Performance, memory, and scaling properties of Sable compared to the Multi-Agent Transformer (MAT) (Wen et al., 2022), the previous state-of-the-art, aggregated over 45 cooperative MARL tasks. Left: Sable ranks best in 34 out of 45 tasks, outperforming all other MARL algorithms tested across 6 environments: RWARE, LBF, MABrax, SMAX, Connector, and MPE. MAT ranked best of 3/45. Middle: Sable exhibits superior throughput, processing up to 6.5 times more steps per second compared to MAT as we scale to 512 agents. Right: Sable scales efficiently to thousands of agents, maintaining stable performance, while using GPU memory significantly more efficiently than MAT.

Bimodal masked language modeling for bulk RNA-seq and DNA methylation representation learning

Maxence Gélard | Hakim Benkirane | Thomas Pierrot | Guillaume Richard | Paul-Henry Cournède

ICML 2025 Workshop Jul 2025
Figure 1: MOJO pipeline. (a) Each modality is first tokenized using linear binning. (b) MOJO, whose core architecture is composed of a mix of convolution and attention operations, is firstly pre-trained through bimodal masked language modeling. (c) Embeddings are probed from MOJO to fine-tune a task-specific head tailored for cancer-type classification or survival analysis.

ChatNT: A Multimodal Conversational Agent for DNA, RNA and Protein Tasks

Bernardo P. de Almeida | Guillaume Richard | Hugo Dalla-Torre | Christopher Blum | Lorenz Hexemer | Priyanka Pandey | Stefan Laurent | Chandana Rajesh | Marie Lopez | Alexandre Laterre | Maren Lang | Uğur Şahin | Karim Beguir | Thomas Pierrot

Nature Machine Intelligence (2025) Jul 2025
ChatNT, the first multimodal conversational agent with an advanced understanding of biological sequences. ChatNT achieves new state-of-the-art results on the Nucleotide Transformer benchmark while being able to solve all tasks at once, in English, and to generalize to unseen questions.

Unified framework for matchgate classical shadows

Valentin Heyraud | Héloise Chomet | Jules Tilly

npj Quantum Information Jul 2025
Unified framework for matchgate classical shadows

Leveraging State Space Models in Long Range Genomics

Matvei Popov | Aymen Kallala | Anirudha Ramesh | Narimane Hennouni | Shivesh Khaitan | Rick Gentry | Alain-Sam Cohen

ICLR LMRL (2025) May 2025
Comparison of the extrapolation methods of state-space models and attention-based models on VEP eQTLs (AUROC). For NTv2, we also reported an inference-time extrapolation method: position interpolation. A dotted vertical line indicates the fine-tuning sequence length (12 kbp) of all models. Attention-based models collapse when processing sequences that are longer than what they have encountered at training time, whereas state-space models show an ability to generalize to sequences up to 10x longer. Lines that turn into dotted indicate values that we were unable to compute due to computational cost constraints and are therefore assumed based on trends.

Open-Source and FAIR Research Software for Proteomics

Lukas Käll | Yasset Perez-Riverol | Wout Bittremieux | William S. Noble | Lennart Martens | Aivett Bilbao | Michael R. Lazear | Bjorn Grüning | Daniel S. Katz | Michael J. MacCoss | Chengxin Dai | Jimmy K. Eng | Robbin Bouwmeester | Michael R. Shortreed | Enrique Audain | Timo Sachsenberg | Jeroen Van Goey | Georg Wallmann | Bo Wen | William E. Fondrie

May 2025
Open-source software (OSS), aligned with the FAIR Principles (Findable, Accessible, Interoperable, Reusable), offers a solution by promoting transparency, reproducibility, and community-driven development, which fosters collaboration and continuous improvement. In this manuscript, we explore the role of OSS in computational proteomics, its alignment with FAIR principles, and its potential to address challenges related to licensing, distribution, and standardization.

AbBFN2: A flexible antibody foundation model based on Bayesian Flow Networks

Bora Guloglu | Miguel Bragança | Alex Graves | Scott Cameron | Timothy Atkinson | Liviu Copoiu | Alexandre Laterre | Thomas D. Barrett

May 2025

Metalic: Meta-Learning In-Context with Protein Language Models

Jacob Beck | Shikha Surana | Manus McAuliffe | Oliver Bent | Thomas D. Barrett | Juan Jose Garau Luis | Paul Duckworth

ICLR 2025 Apr 2025
Our method, called Metalic (Meta-Learning In-Context), uses in-context learning and fine-tuning, when data is available, to adapt to new tasks.

Simple Guidance Mechanisms for Discrete Diffusion Models

Hugo Dalla-Torre | Sam Boshar | Bernardo P. de Almeida | Thomas Pierrot | Yair Schiff | Subham Sekhar Sahoo | Hao Phung | Guanghan Wang | Alexander Rush | Volodymyr Kuleshov

ICLR 2025 Apr 2025
Guidance mechanisms for discrete diffusion

De novo peptide sequencing with InstaNovo: Accurate, database-free peptide identification for large scale proteomics experiments

Kevin Eloff | Konstantinos Kalogeropoulos | Oliver Morell | Amandla Mabona | Jakob Berg Jespersen | Wesley WIlliams | Sam P. B. van Beljouw | Marcin Skwark | Andreas Hougaard Laustsen | Stan J. J. Brouns | Stan J. J. Brouns | Erwin M. Schoof | Jeroen Van Goey | Ulrich auf dem Keller | Karim Beguir | Nicolas Lopez Carranza | Timothy P. Jenkins

Nature Machine Intelligence Mar 2025